Key Takeaways
- Official per-token prices (as of Sep 20, 2026; newer models have launched since): Claude Sonnet 5 $2 / $10 per million tokens (input/output), Claude Opus 5 $5 / $25, Gemini 2.5 Flash $0.30 / $2.50, GPT-5.6 Sol $4 / $20 (promotional through at least Nov 21, 2026), GPT-5.6 Terra $2 / $12, and GPT-5.6 Luna $0.20 / $1.20.
- Output-to-input price ratios range from 5x to about 8.3x in this comparison; the multiplier is not universal across providers or models.
- Batch processing cuts Claude prices in half; prompt-cache hits cost 10% of the base input rate on most Claude models.
- We have not measured our own spend or cache-hit rate. Every figure here is a vendor list price or our own arithmetic on stated token counts, so no monthly spend figure is claimed.
- Prices have moved since the Sep 20 rate card. On Oct 2, 2026, Claude Opus 5.5 lists at $4 / $20 (Opus 5: $5 / $25), cutting the 4,000 + 3,000-token article from $0.095 to $0.076; see the table below.
Every price below comes from a vendor’s own page: Anthropic’s pricing documentation, OpenAI’s per-model pages for the GPT-5.6 tiers, and Google’s Gemini API pricing page. The 4,000-input, 3,000-output article is our assumption, not a measurement, so replace it with your own token counts before drawing conclusions.
Official Rate Card (as published Sep 20, 2026)
| Model | Input / MTok | Output / MTok | Output ÷ Input |
|---|---|---|---|
| Claude Opus 5 | $5.00 | $25.00 | 5.0x |
| Claude Sonnet 5 | $2.00 | $10.00 | 5.0x |
| Claude Haiku 4.5 | $1.00 | $5.00 | 5.0x |
| GPT-5.6 Sol | $4.00 | $20.00 | 5.0x |
| GPT-5.6 Terra | $2.00 | $12.00 | 6.0x |
| GPT-5.6 Luna (post-cut) | $0.20 | $1.20 | 6.0x |
| Gemini 2.5 Flash | $0.30 | $2.50 | 8.3x |
Sources: the official Anthropic, OpenAI, and Google pricing documentation cited below. The GPT-5.6 rows cover three tiers (Sol, Terra and Luna), not the full OpenAI catalog. GPT-5.6 Sol’s $4 / $20 is promotional through at least November 21, 2026, and “post-cut” for Luna means after OpenAI’s July 30, 2026 price reduction.
Direct Calculation: What One Article Actually Costs
Take a realistic content task: research and draft a ~1,500-word article, roughly 4,000 input tokens (source material, prior context, instructions) and 3,000 output tokens (the draft itself). At list price, no caching, no batching:
| Model | Input cost | Output cost | Total |
|---|---|---|---|
| Claude Opus 5 | 4,000 × $5/1M = $0.020 | 3,000 × $25/1M = $0.075 | $0.095 |
| Claude Sonnet 5 | 4,000 × $2/1M = $0.008 | 3,000 × $10/1M = $0.030 | $0.038 |
| Gemini 2.5 Flash | 4,000 × $0.30/1M = $0.0012 | 3,000 × $2.50/1M = $0.0075 | $0.0087 |
| GPT-5.6 Luna | 4,000 × $0.20/1M = $0.0008 | 3,000 × $1.20/1M = $0.0036 | $0.0044 |
Opus 5 costs roughly 21.6x more per article than GPT-5.6 Luna, and about 2.5x more than Sonnet 5 — for a single draft.
That gap compounds fast at volume: 1,000 articles a month is a ~$57 difference between Sonnet 5 and Opus 5 alone, before counting research passes, revisions, or QA calls that also consume tokens.
This is exactly why routing cheap, high-volume steps (search, first-pass drafts, classification) to Flash- or Luna-tier models and reserving Opus-tier models for judgment calls that are expensive to get wrong is a cost decision, not just a quality one.
How the Input/Output Split Changes the Bill
A task’s cost is input tokens × input price plus output tokens × output price, divided by 1,000,000. The table applies that formula to four workload shapes at two rate cards from this page. The token counts are illustrative assumptions of ours, not measurements; swap in your own.
| Input + output tokens | Claude Sonnet 5 ($2 / $10) | Gemini 2.5 Flash ($0.30 / $2.50) |
|---|---|---|
| 20,000 + 500 (long document in, short answer out) | $0.045 | $0.00725 |
| 6,000 + 1,000 | $0.022 | $0.0043 |
| 4,000 + 3,000 (the article above) | $0.038 | $0.0087 |
| 1,000 + 6,000 (short prompt, long generation) | $0.062 | $0.0153 |
Output is 11% of the Sonnet 5 bill at 20,000 + 500 tokens but 97% at 1,000 + 6,000. For Flash the same shapes give 17% and 98%, because its output price is 8.3x its input price.
Sonnet 5 costs 6.2x Flash on the input-heavy shape and 4.1x on the output-heavy one.
Opus 5 costs exactly 2.5x Sonnet 5 on every shape, because both its input and output prices are 2.5x higher. For a monthly estimate, multiply the per-task cost by task volume: 2,000 tasks at $0.038 is $76 on Sonnet 5 at list price, before caching or batch discounts.
Agent loops that re-send their context at every step push the input side up sharply. Why AI Agents Cost More Than Chatbots: 4x the Tokens works through that case with Sonnet 5 rates, so this page does not repeat it.
Prices Since Publication (checked October 2, 2026)
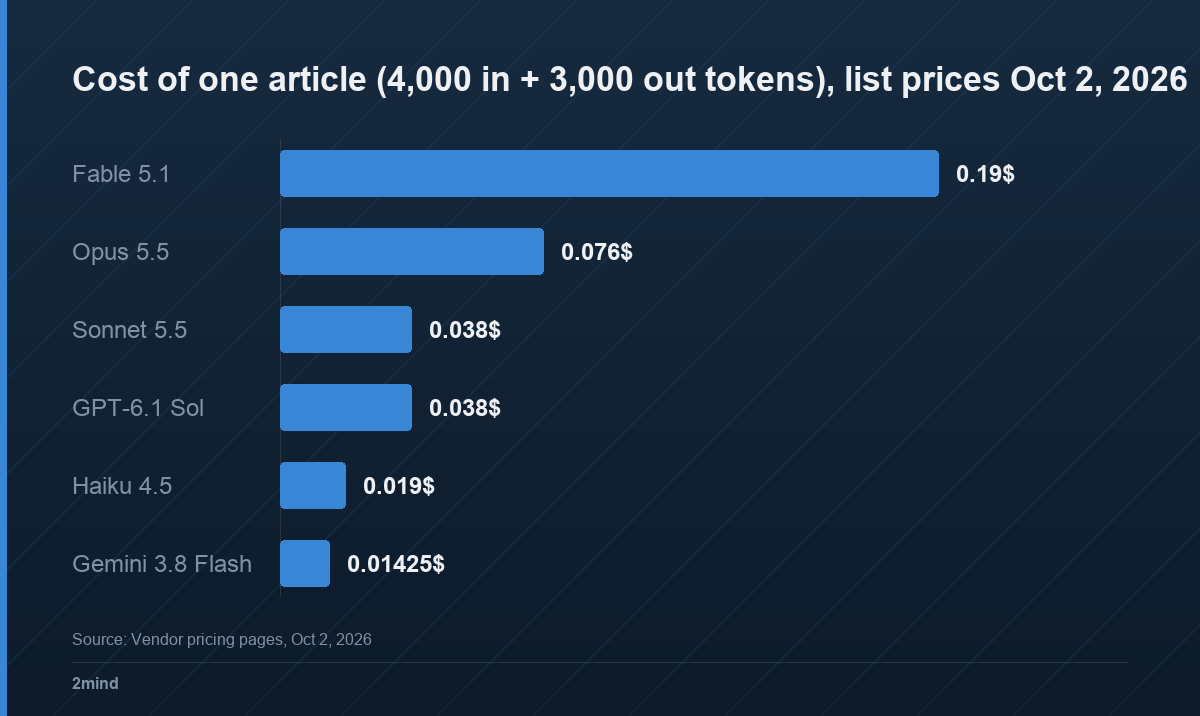
The rate card above is dated September 20. The table lists current list prices read from the vendors’ pages on October 2, 2026, with the same article: 4,000 input and 3,000 output tokens, no caching or batching.
| Model | Input / output per MTok | Cost per article |
|---|---|---|
| Claude Fable 5.1 | $10 / $50 | $0.19 |
| Claude Opus 5.5 | $4 / $20 | $0.076 |
| Claude Sonnet 5.5 | $2 / $10 | $0.038 |
| Claude Haiku 4.5 | $1 / $5 | $0.019 |
| GPT-6 Astra | $10 / $50 | $0.19 |
| GPT-5.6 Sol (promotional) | $4 / $20 | $0.076 |
| GPT-6.1 Sol | $2 / $10 | $0.038 |
| GPT-6 Luna | $0.10 / $0.50 | $0.0019 |
| Gemini 3.8 Flash (introductory) | $0.75 / $3.75 | $0.01425 |
Opus 5.5 lists at $4 / $20 against Opus 5’s $5 / $25, which takes the article from $0.095 to $0.076, a 20% cut. Sonnet 5.5 keeps Sonnet 5’s $2 / $10.
OpenAI’s page calls GPT-5.6 Sol’s price promotional through at least November 21, 2026 and does not state the later price.
Conditions: Gemini 3.8 Flash is listed at $0.75 / $3.75 through December 31, 2026 and $1.50 / $7.50 from January 1, 2027. GPT-6.1 Sol’s price applies to prompts up to 272K input tokens; longer prompts cost more.
Anthropic says Claude 4.7 and later models use a tokenizer that produces about 30% more tokens for the same text than earlier Claude models. A fixed token count therefore does not describe the same article on every model, so treat cross-vendor per-article costs as approximations.
Two Lenses
Through the buyer’s lens
The list price is the start of the estimate, not the end. Two workloads with identical token totals can differ several-fold in cost depending on how much of the total is output and how much of the input is cache-eligible. Before comparing vendors, split your own workload into input, output, and repeated-context tokens — the split moves the bill more than the vendor choice does.
Through the rate-card’s lens
Across all three vendors in our table, output stays at 5–8.3x the input rate — no vendor sells output at parity. Any comparison quoting one blended per-token number is therefore making a hidden assumption about your output share, and it flatters whichever model that assumption favors. Reading the two columns separately is the only vendor-neutral way to use a rate card.
What Would Change Our View
Prompt caching and batch processing can cut these numbers sharply — Claude’s batch API halves both input and output prices, and cached input reads cost 10% of the base input rate on Sonnet and Haiku models (5% on Opus 5.5, 2.5% on Fable 5.1, per Anthropic’s pricing page).
If a workload is repetitive enough to cache well, the effective cost gap between tiers narrows. We have not measured our own cache-hit rate in this piece; that would change the real-world total more than the list price does.
FAQ
Q. Why is GPT/Claude output priced so much higher than input?
A. The official rate cards charge different prices for input and output. They show 5–8.3x output-to-input ratios for the models compared here, but the rate cards do not by themselves establish one universal technical cause.
Q. Is Gemini 2.5 Flash always cheaper than Claude or GPT?
A. At list price for equivalent token counts, yes against every tier compared here except GPT-5.6 Luna, which is cheaper still. But “cheaper per token” isn’t the same as “cheaper per task” if a smaller model needs more retries or produces a lower-quality first draft that then needs a second, pricier pass to fix.
Q. How much does it actually cost to run an AI agent for a month?
A. It depends entirely on volume and which tier handles which step — there’s no single answer. Multiply your expected input/output tokens per task by the rate card above, by task count, per model actually used; that is the only reliable estimate.
Q. Have these prices changed since September 20?
A. For some models, yes. Claude Opus 5.5 lists at $4 / $20 against Opus 5’s $5 / $25, and newer OpenAI and Google models have appeared. Several current prices are promotional or introductory, so check the vendor pages listed in the sources before budgeting.
Sources
- Claude API Pricing — Anthropic, official pricing page, checked Sep 2026
- OpenAI API Models — OpenAI, official model pricing, checked Sep 2026
- Gemini Developer API Pricing — Google, official pricing page, checked Sep 2026 and Oct 2, 2026 (Gemini 3.8 Flash)
- Claude pricing — Anthropic, accessed Oct 2, 2026 (Fable 5.1, Opus 5.5, Sonnet 5.5, Haiku 4.5)
- OpenAI API pricing — OpenAI, accessed Oct 2, 2026 (GPT-5.6 Sol, GPT-6 Astra, GPT-6.1 Sol, GPT-6 Luna)
- GPT-5.6 Sol model page — OpenAI, accessed Oct 2, 2026 (promotional pricing through at least Nov 21, 2026; Terra and Luna have sibling pages)
- OpenAI API changelog — OpenAI, July 30 and September 29, 2026 entries
Correction, October 2, 2026. An earlier version said Gemini 2.5 Flash is cheaper than every tier compared; GPT-5.6 Luna is cheaper still. GPT-5.6 Sol’s $4/$20 price is promotional through at least November 21, 2026, and the rate card is dated September 20, 2026.
Update, October 2, 2026. Title reworded from “The Token Cost Nobody Shows You” to describe the content. Added the input/output sensitivity table and the table of prices since publication; removed an unsupported comparison with aggregator sites and a section that repeated the output-ratio point.
Leave a Reply